A data science team spends six weeks building a model, only to watch it underperform in production. The algorithm was not the problem. The training data was inconsistent, half-labeled, and full of formatting mismatches nobody caught until the model started making strange predictions. This happens more often than most AI teams admit, and it almost always traces back to the same root cause: data wrangling that was rushed, skipped, or treated as an afterthought.
Data wrangling is not the glamorous part of AI development. It rarely gets a headline or a demo day slide. But it is the single biggest factor separating models that work in the real world from models that only work in a notebook.
What Data Wrangling Actually Means
Data wrangling is the process of taking raw, messy, inconsistent data and transforming it into a clean, structured format a model or analytics system can actually use. It covers a wide range of tasks: cleaning missing or duplicate values, standardizing formats across sources, merging datasets that were never designed to talk to each other, and converting unstructured inputs like video, audio, or free text into something machines can process reliably.
It is easy to underestimate how much of an AI project this consumes. Industry surveys of data scientists consistently show that data preparation, not model building, takes up the largest share of project time. Teams that treat this stage as a quick checkbox usually pay for it later, either through poor model accuracy or through expensive rework once problems surface in production.
Why Poor Data Wrangling Breaks AI Projects
The damage from weak data wrangling rarely shows up immediately. It shows up weeks or months later, when a model trained on inconsistent data starts producing unreliable outputs in the field.
A few patterns explain most of these failures. Inconsistent labeling means the same concept gets tagged differently across different parts of a dataset, confusing the model about what it is actually learning. Missing context strips away information a human would use to interpret ambiguous cases, like sarcasm in text or partial occlusion in video. Format mismatches between data sources create silent errors that do not throw a warning, they just quietly corrupt downstream calculations. Unrepresentative sampling skews a model toward whatever was easiest to collect, not what actually reflects real-world conditions.
None of these are algorithm problems. They are data discipline problems, and no amount of model tuning fixes them.
Market Context: Why This Matters More in 2026
AI adoption has moved from experimentation to production at a pace that has outrun most teams’ data infrastructure. Enterprises are now running generative AI and machine learning models in customer-facing environments, regulated industries, and high-stakes decision workflows where a hallucination or biased output carries real consequences.
That shift has raised the bar for data quality. A chatbot prototype can tolerate messy training data. A production system making financial recommendations, medical triage suggestions, or compliance decisions cannot. Regulators and enterprise buyers are increasingly asking not just “does the model work” but “can you prove the data behind it was validated, labeled consistently, and free of known bias.” Data wrangling has quietly become a governance requirement, not just a technical nicety.
The Core Stages of Data Wrangling
A reliable data wrangling process generally moves through a consistent set of stages, even though the specific tools and techniques vary by data type.
Discovery starts the process, where teams assess what data exists, where it lives, and what condition it is in before any cleaning begins. Cleaning follows, removing duplicates, correcting errors, and handling missing values without introducing new bias. Structuring comes next, converting unstructured or semi-structured data (video, audio, free text, scanned documents) into consistent, model-ready formats. Enriching adds labels, tags, and contextual metadata that give the data meaning beyond raw values. Validating closes the loop, checking the final dataset against quality benchmarks before it ever reaches a model.
Skipping or rushing any one of these stages tends to resurface later, usually at the worst possible time, which is why mature AI teams build wrangling into their pipeline as a repeatable process rather than a one-time cleanup project.
Data Wrangling for Unstructured Media
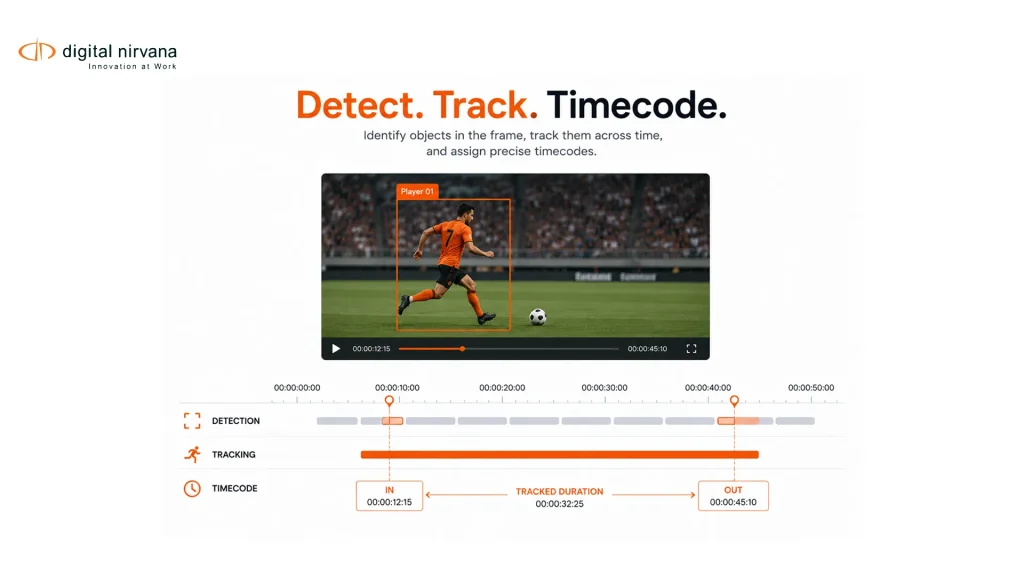
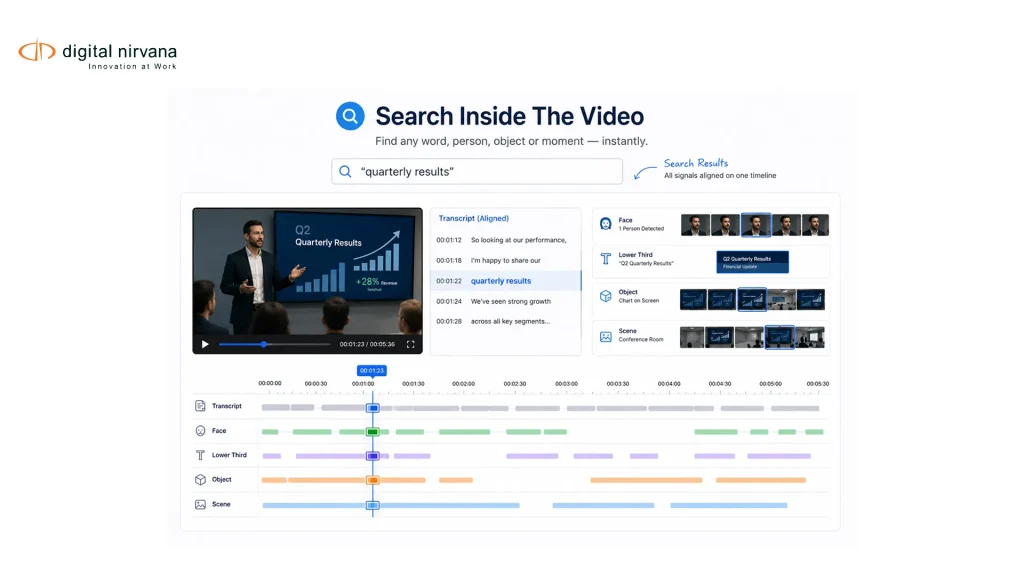
Text and tabular data get most of the attention in data wrangling conversations, but media-heavy organizations face a harder version of the same problem. Video, audio, and image data do not come with clean rows and columns. They require transcription, scene detection, object recognition, and speaker labeling before they can even be structured, let alone cleaned.
This is where AI-powered microservices make a measurable difference. Tools like MediaServicesIQ apply automated speech-to-text, OCR, and object and face detection to raw video and audio, generating the structured metadata layer that wrangling workflows depend on. Without this step, teams attempting to prepare video or audio for AI training end up doing it manually, frame by frame, which simply does not scale.
For organizations working with large archives that need to be transformed into training-ready datasets, MetadataIQ provides the indexing and search layer that makes it possible to locate, filter, and export the right subset of content instead of processing an entire archive indiscriminately.
Common Mistakes Teams Make During Data Wrangling
A handful of mistakes show up repeatedly across AI teams, regardless of industry.
Treating data cleaning as a one-time task instead of an ongoing pipeline, so new data entering the system after launch quietly degrades quality over time. Skipping documentation of what transformations were applied, which makes it nearly impossible to trace a model error back to a specific data decision. Over-relying on fully automated labeling without human spot-checks, especially for nuanced or high-stakes categories where automated tools consistently underperform. Ignoring class imbalance, where rare but important cases get diluted by an overwhelming majority of common examples, teaching the model to ignore exactly the scenarios it most needs to catch.
How Human-in-the-Loop Review Strengthens Data Quality
Fully automated data wrangling sounds efficient, but for anything beyond straightforward numeric cleanup, it tends to introduce its own errors. Automated labeling tools can misclassify ambiguous cases, and automated cleaning scripts can strip out data that looks like noise but is actually a meaningful edge case.
The more reliable approach pairs automation with structured human review. This is the model behind Data Intelligence services, which combine AI-assisted data wrangling, labeling, and validation with domain-aware human reviewers who catch what automated pipelines miss. For teams already running models in production, this same discipline extends into Managed AI operations, where human-in-the-loop review continues after deployment, monitoring for drift, hallucination, and bias in live outputs rather than treating data quality as a problem solved once at training time.
A Practical Data Wrangling Checklist
- [ ] Audit source data for missing values, duplicates, and inconsistent formats before starting any cleaning
- [ ] Standardize naming conventions and units across all merged data sources
- [ ] Convert unstructured media into structured, searchable metadata before attempting to label it
- [ ] Apply consistent labeling guidelines, documented in writing, across every annotator or automated tool
- [ ] Spot-check automated labels with human reviewers, especially for ambiguous or high-stakes categories
- [ ] Check for class imbalance and correct sampling before training begins
- [ ] Document every transformation applied, so errors can be traced back to their source
- [ ] Validate the final dataset against quality benchmarks before it reaches a model
Implementation Considerations for Building a Wrangling Pipeline
Teams building or upgrading a data wrangling pipeline should think in terms of infrastructure, not just process. Where will cleaned and structured data be stored, and does that environment scale with growing data volume? Cloud infrastructure that can handle spikes in data processing without manual scaling matters here, which is why data wrangling initiatives often run alongside broader Cloud Engineering modernization work rather than as a standalone project.
Ownership also matters. Data wrangling that falls between teams, with no clear owner for quality standards, tends to drift over time. Assigning a specific team or role responsibility for data quality benchmarks keeps the pipeline accountable as data volume grows.
Where Digital Nirvana Fits Into Your Data Strategy
Reliable AI outcomes depend on a data foundation most teams underinvest in until something breaks. Digital Nirvana’s Data Intelligence services are built around exactly this gap, combining prompt engineering, data labeling, and model validation with human-in-the-loop review that catches what automated tools miss. For media-heavy organizations, that same discipline extends naturally into transforming video and audio through MediaServicesIQ and MetadataIQ, turning unstructured content into training-ready, searchable data without requiring teams to build that capability from scratch.
How This Aligns With Digital Nirvana’s Broader Expertise
Data wrangling is not a task that ends once a model ships. It is an ongoing operational discipline, and that mirrors how Digital Nirvana approaches AI reliability across its full product suite. The same human-in-the-loop principle that strengthens data labeling in Data Intelligence also governs production AI monitoring in Managed AI, ensuring models stay accurate as real-world data continues to evolve after launch. Organizations exploring how this translates into measurable outcomes can review examples in Digital Nirvana’s success stories, and teams building out the broader operational capacity behind these workflows often pair data initiatives with Managed Talent support to scale review and annotation work without overextending internal headcount.
Conclusion
Data wrangling will never be the most exciting part of an AI initiative, but it is consistently the part that determines whether the initiative actually works. Teams that treat it as a repeatable, well-documented process, backed by both automation and human review, build models that hold up in production instead of models that only perform well in a demo. Getting the data right first is not a delay to building better AI. It is the fastest path to it.
Key Takeaways
- Data wrangling, not model architecture, is usually the biggest factor behind poor AI performance.
- Inconsistent labeling, missing context, and format mismatches cause silent errors that surface later in production.
- Unstructured media like video and audio requires additional steps (transcription, scene detection, object recognition) before it can be wrangled effectively.
- Fully automated wrangling introduces its own errors; pairing automation with human review produces more reliable results.
- A documented, repeatable wrangling pipeline prevents data quality from drifting after a model launches.
- Data quality is increasingly a governance requirement, not just a technical best practice.
FAQ
How much of an AI project’s time is typically spent on data wrangling? Data preparation consistently takes up the largest share of AI project time, often more than model building and tuning combined, according to widely cited data science surveys.
Is data wrangling only relevant for structured, tabular data? No. Unstructured media like video, audio, and scanned documents require additional preprocessing, including transcription and object detection, before they can be wrangled into a usable format.
Can data wrangling be fully automated? Parts of it can, but high-stakes or ambiguous data generally benefits from human-in-the-loop review to catch errors automated tools miss, especially around labeling accuracy and class imbalance.